Research and engineering foundation
Portfolio / 02 · Large language model project
Black Hole LLM.
An evolving language-model initiative focused on the foundations that make experimentation repeatable: tokenization, corpus preparation, model configuration, training, checkpoints, evaluation and careful iteration.
Full product study · Context → Strategy → Experience → Engineering → Validation
01 / The brief
Begin with the problem
the product must solve.
A language model is not built by architecture code alone. Training results depend on data quality, tokenizer behaviour, configuration, resource constraints, checkpoint integrity, evaluation and reproducibility. Without a dependable loop, it is difficult to distinguish a genuine model improvement from a data, code or measurement problem.
Make model development observable and repeatable
Training can consume scarce compute for a long time, making hidden failures costly. Data, tokenizer, sequence length, architecture, optimizer, schedule and checkpoint state must agree. A good engineering foundation makes configuration explicit, saves recoverable state, logs useful metrics and makes a run understandable after interruption.
Treat data, training and evaluation as one pipeline
The model lifecycle begins before the first training step. Corpus quality, duplication, document boundaries, token distribution and dataset splits affect what the model learns. Tokenization and block preparation need validation, while training metrics and checkpoint metadata help connect observed behaviour to a specific run.
Protect scarce resources while keeping experiments informative
Memory and throughput constraints shape batch sizing, sequence length, precision, checkpoint intervals and evaluation frequency. The system should fail clearly when assumptions are invalid, save enough state to resume safely and avoid reporting a checkpoint as healthy merely because it exists on disk.
Improve capability through measurable, controlled iteration
The intent is an evolving development loop: choose a weakness, form a hypothesis, implement a bounded change, evaluate against a stable comparison set, inspect regressions and promote changes only when evidence supports them. Autonomy is not a substitute for evaluation, security boundaries or reproducibility.
What this study does—and does not—claim
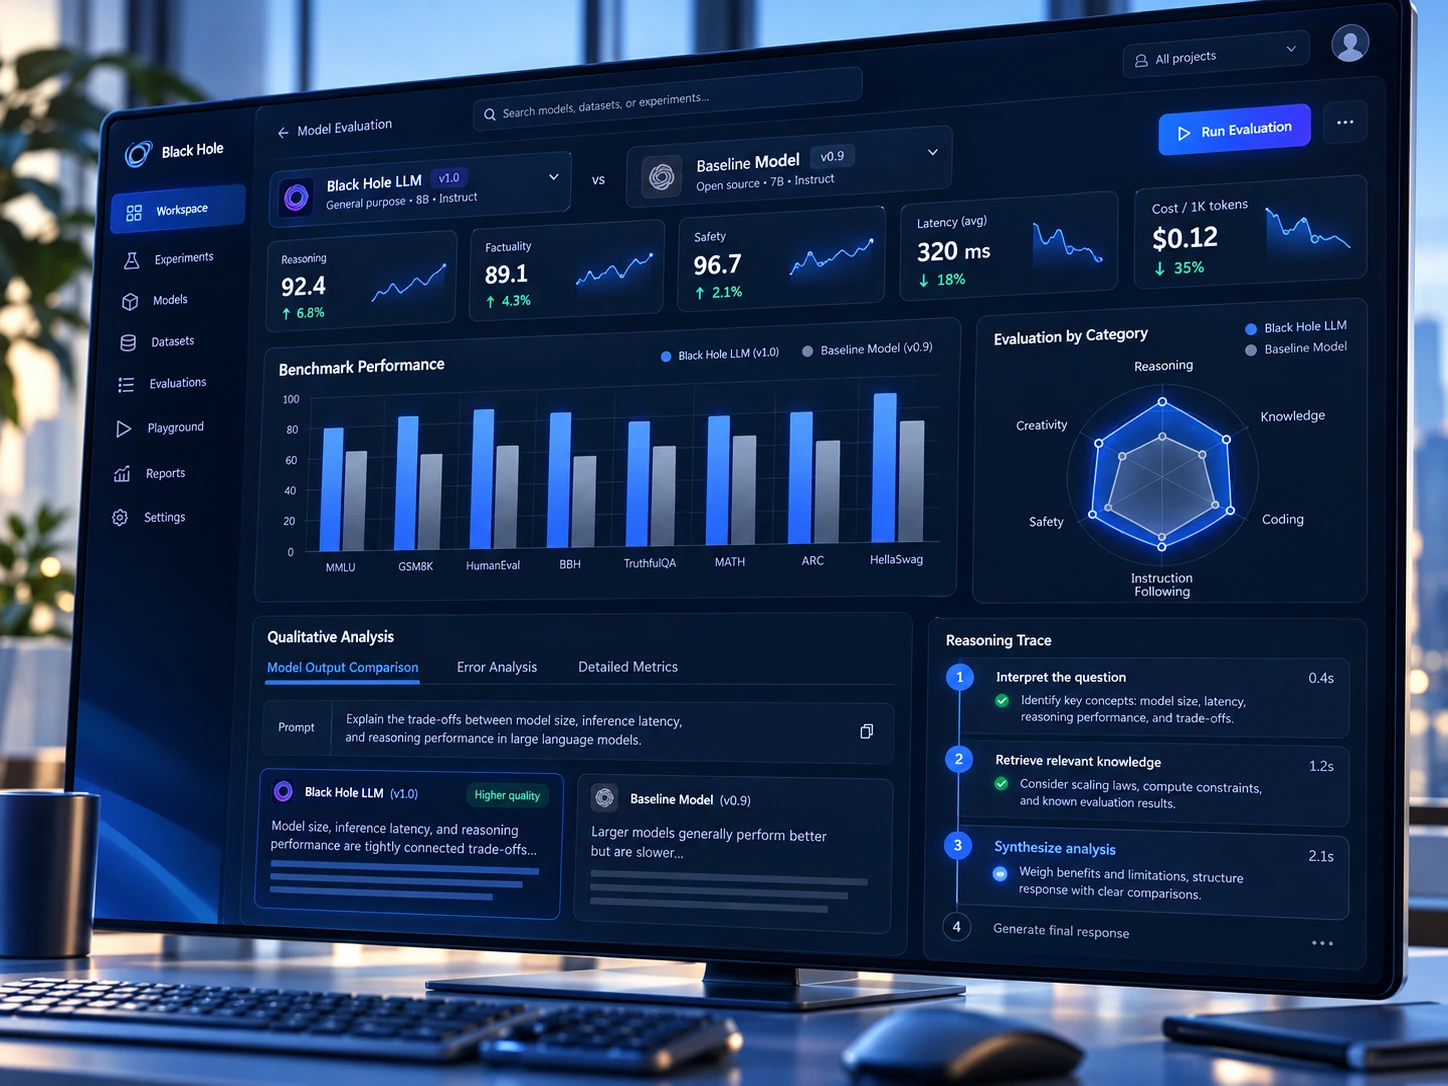
This case study describes an evolving R&D foundation, not a claim that the model matches mature commercial systems. Model size, training progress, benchmark results and capabilities should be published only with run-specific evidence and clear evaluation methodology.
02 / Product structure
The model-development system and its responsibilities.
These components form a chain; an issue upstream can look like a model problem downstream, so each layer needs independent checks.
Corpus and data contracts
Define accepted sources, cleaning rules, document boundaries, deduplication, validation, splits and provenance. Keep raw, processed and tokenised artefacts distinguishable.
Tokenizer correctness
Version vocabulary and tokenization assets, test encode/decode behaviour, inspect unknown or malformed inputs and verify special token handling before large runs.
Model configuration
Make vocabulary size, context length, layer/head shape, embedding strategy, dropout and positional configuration explicit and validated before allocation.
Training loop and resource management
Track optimizer and scheduler state, gradients, throughput, loss and memory. Handle interruption and out-of-resource conditions deliberately instead of silently writing incomplete checkpoints.
Checkpoint and experiment records
Store model state with enough configuration, step, optimizer/scheduler state and run metadata to resume or compare experiments safely. Verify restore paths with actual smoke tests.
Evaluation and capability claims
Maintain held-out examples and task-specific tests. Report configuration and limitations with results, track regressions and avoid using training loss alone as proof of useful language ability.
03 / End-to-end process
From experiment design to a reproducible model iteration.
Each phase produces traceable evidence that helps make the next training decision defensible.
01
Define the experiment question
Write the capability or engineering question, baseline, hypothesis, available compute, success criteria and rollback condition before modifying the run.
Deliverable: experiment brief and comparison plan.
02
Audit and prepare the corpus
Validate source provenance, text quality, duplicates, boundaries, splits, token counts and storage format; record the exact data version.
Deliverable: versioned dataset manifest and data-quality report.
03
Validate tokenization and shapes
Run tokenizer round trips and sample inspection; assert vocabulary, sequence, tensor and model configuration compatibility before a full run.
Deliverable: tokenizer tests and configuration validation.
04
Run a small reproducible smoke test
Exercise forward/backward passes, loss computation, gradients, optimizer updates, checkpoint save/restore and metric logging on a small workload.
Deliverable: passing smoke run and verified checkpoint path.
05
Scale training within resource limits
Choose batch/sequence/checkpoint intervals around measured memory and throughput. Track train/evaluation signals and stop safely when a run deviates from expected conditions.
Deliverable: traceable run with metrics and resource observations.
06
Validate resume and recovery
Interrupt a test run deliberately, restore it and verify step, model and optimizer/scheduler state. Check that written artifacts are complete and identifiable.
Deliverable: tested recovery procedure and checkpoint manifest.
07
Evaluate model behaviour
Use held-out language and task samples, compare to a baseline, inspect failure classes, and separate data memorisation or loss movement from demonstrated task quality.
Deliverable: evaluation report and regression list.
08
Promote, reject or repeat
Record the decision, limitations and next hypothesis. Keep the baseline available, preserve run provenance and promote changes only when evaluation evidence justifies it.
Deliverable: experiment decision record and next iteration plan.
04 / Experience principles
Decisions that keep the product coherent.
These principles are the tests used to judge design and implementation choices, especially when a feature competes with clarity, trust or the core job.
Reproducibility over mystery
Every significant run should point to the exact code revision, dataset, tokenizer, configuration, seed when applicable and saved state.
A checkpoint is a recovery contract
A file should be loadable, compatible and accompanied by enough metadata to explain how it was produced and resumed.
Metrics need context
Training loss, evaluation loss, throughput and task behaviour answer different questions. State what was measured and what a metric cannot prove.
Capability grows through evaluation
Changes should be compared to a stable baseline, tested for regression and reversed when evidence shows a meaningful decline.
05 / Quality and validation
How the work is checked before it earns trust.
Validation should be planned against real tasks and credible failure modes. The checks below describe how this product direction should be evaluated; they are not fabricated claims that every test has already passed.
Data provenance and splits
Sources and processing are documented, duplicate leakage is considered and evaluation data is kept separate from training where the protocol requires it.
Tokenizer and configuration validity
Round trips, special tokens, vocabulary dimensions, sequence lengths and model parameter shapes are tested before expensive training.
Training stability
Gradient, loss, learning rate, throughput and resource signals are logged; unexpected values trigger investigation rather than being ignored.
Checkpoint recoverability
A saved state can be loaded and used to resume from the expected step with the intended model and optimizer state.
Evaluation quality
Held-out tests, qualitative error inspection and regression comparisons are documented with limitations and reproducible settings.
Resource and security controls
Training jobs, datasets, checkpoints and logs have clear storage, access, retention and cleanup rules appropriate to the environment.
06 / Evidence and next steps
How progress should be demonstrated
No benchmark or capability score is claimed here. Progress should be reported with reproducible evidence tied to a clearly described run.
Current direction: research and engineering work on tokenizer, training-engine, model-configuration, checkpoint and evaluation foundations. The next maturity step is to make every stage reproducible and to publish capabilities only when stable evaluations support the claim.
Signals worth measuring
- A training run starts from a validated configuration and produces interpretable metrics.
- A checkpoint can be restored and resumed without silently losing relevant state.
- A change is compared against a stable baseline on held-out evaluation tasks.
- Reported improvements include the evaluation method, run settings and observed regressions.
- Resource use and failure modes can be traced through logs and checkpoint metadata.
- Model capability claims match measured behaviour and explicitly state known limitations.
Next milestones
- 01Stabilise data, tokenizer, configuration and checkpoint contracts.
- 02Expand smoke, resume and regression tests around real training runs.
- 03Establish consistent held-out evaluations and a model behaviour report.
- 04Use experiment records to choose improvements and maintain safe rollback paths.