Problem before model
Start with the job to be done and the value it should create.
Intelligent systems, AI agents and machine-learning products designed for real-world impact.
We approach AI as a product capability, not a decoration: clear use cases, understandable behaviour, thoughtful evaluation and meaningful human control.
Start with the job to be done and the value it should create.
Keep outputs understandable and people in control.
Test quality, failure modes and real-world usefulness.
Treat privacy, reliability and safety as product requirements.
Start with the outcome. Then shape the right experience, tools and technical foundation around it.
Discuss a project
Context-aware assistance for questions, summaries, drafting, research and guided actions with clear limits and review controls.
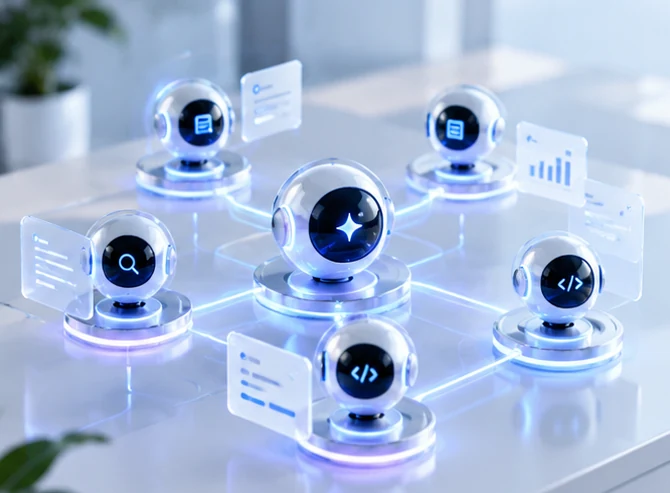
Bounded agents that plan steps, use approved tools, report progress and request confirmation for important actions.
Automation that joins systems and removes repetitive work while retaining retries, logs, exception paths and human oversight.
Interfaces for prompt/model comparison, dataset review, evaluation, tracing and monitoring AI behaviour over time.
Useful AI systems begin with a concrete job and clear limits. Model choice, context, tools, evaluation and human oversight matter as much as the interaction design.
Define the actual user outcome, the acceptable error rate, latency, cost and whether AI is necessary. Choose between an LLM, a smaller classifier, conventional automation or a hybrid workflow.
Ground answers in approved information using structured context, retrieval, document indexing, source attribution and freshness controls. Make it possible to distinguish evidence from a plausible but unsupported answer.
Give agents a bounded objective, typed tool interfaces, permission checks, step limits and clear reporting. Require approval for destructive, financial, external or otherwise consequential actions.
Build representative test sets, compare versions, measure task success and inspect failure classes such as hallucination, tool misuse, missed context, bias and inconsistent outputs.
Show uncertainty where useful, let people review and edit outputs, provide an escape to manual workflows, and avoid making decisions invisible behind a single AI response.
Control what enters prompts, protect secrets and personal data, defend against prompt injection, monitor usage and errors, and plan for model or provider changes.
We build evidence in stages, keeping risky actions bounded and treating evaluation as a continuous engineering activity rather than a final demo.
Describe user, context, input/output, expected behaviour, unacceptable failure, cost/latency constraints and whether the task truly needs AI.
Output: task specification and risk classification.Compare a hosted model, local model, fine-tuned model, retrieval system, conventional automation or a hybrid approach against constraints and evidence.
Output: model rationale and baseline evaluation plan.Review source quality, access rights, sensitive data, data freshness, retrieval structure, citation needs and evaluation examples.
Output: data/context plan and representative test set.Design prompt/response flow, progress, sources, uncertainty, correction, escalation, approval and fallback so the user retains agency.
Output: interaction design and failure-state map.Build constrained prompts, structured outputs, retrieval, tool contracts, timeouts, validation, retries, permissions and state tracking.
Output: integrated AI workflow with explicit boundaries.Test realistic tasks, ambiguous input, missing context, adversarial attempts, tool errors, permission boundaries and regressions across versions.
Output: evaluation report and known limitations.Add logging without leaking secrets, rate limits, human approval, monitoring, cost budgets, abuse controls and rollback for model/configuration changes.
Output: launch guardrails and operating playbook.Use a controlled rollout, review user feedback and error traces, compare quality and cost to baselines, then improve or disable weak behaviours.
Output: monitored release and ongoing evaluation cycle.AI engineering combines software reliability with evaluation of probabilistic behaviour. It needs explicit failure handling instead of assuming every output is right.
Representative examples, gold answers or rubrics, edge cases, version comparisons and regression checks.
Document ingestion, chunking, ranking, access-aware retrieval, citations and refresh strategies when source material changes.
Schema validation, allow-listed tools, scoped credentials, step budgets, rate limits and approvals for risky actions.
Data minimisation, redaction where necessary, secret handling, output checks and testing for prompt injection or misuse.
Latency, cost, token and tool usage, error classes, refusals, user feedback and traceable workflow steps.
Versioned prompts/configurations, model/provider fallbacks, repeatable evaluation and rollback when quality regresses.
An AI system combines a model with context, tools, permissions, data flows, user experience, evaluation and monitoring. We begin with the task and its risk, determine whether AI is appropriate, and design clear boundaries so people can understand what the system knows, what it has done and when a human must remain in control.
We define the user outcome, input quality, acceptable error, latency, cost and consequences of a wrong answer. Some tasks are better solved through ordinary software, deterministic rules or a smaller classifier; others justify generative models or a hybrid. Evaluation criteria are agreed before optimization so impressive examples do not conceal fragile behaviour.
If the system needs proprietary or changing information, we plan ingestion, structure, retrieval, access permissions, freshness and source display. Data quality and retrieval evaluation are as important as prompt writing. We also define which sources are authoritative, what the model should do when evidence is missing and how it should express uncertainty.
An agent needs a clear objective, tool schemas, scoped credentials, step limits, timeouts and a recovery strategy. Tool calls must be validated and consequential actions may need human confirmation. State and action history should make behaviour inspectable; the system must never claim that an external task succeeded merely because it generated an intention to perform it.
We create representative cases, adversarial examples and regression checks, then track task success, factual errors, refusal quality, latency, cost and tool failures. Prompts, model versions and retrieval configuration need change control. Monitoring and human review help identify when model behaviour has drifted or when a task should be moved back to a simpler, safer workflow.
A trustworthy AI feature explains its boundaries and provides a controlled fallback when it cannot complete the task reliably.
Representative tests check evidence, citation correctness, freshness and whether the model admits when information is unavailable.
Tool inputs are schema-validated, credentials are scoped, actions are allow-listed and sensitive steps have explicit approval rules.
Test hostile instructions in user input and retrieved content; separate trusted instructions from untrusted data and restrict accessible actions.
Users can inspect, edit, reject or escalate outputs; consequential decisions are not hidden behind an opaque response.
Minimise sensitive data, protect secrets, define retention and monitor token, tool, provider and infrastructure costs.
Keep regression sets and versioned settings, review production failures, and retain a way to revert or disable a degraded capability.
The product must define what intelligence should accomplish, what it may access, how quality is assessed and where human review is required.
Specify the job, users, error tolerance, latency, cost and risk. Choose an LLM, smaller model, conventional automation or hybrid approach based on the actual task rather than novelty.
Connect approved documents or records through structured context and retrieval. Track source authority and freshness, control access at retrieval time and show sources when users need to verify an answer.
Give each agent a bounded objective, typed tool contracts, time/step limits, permission checks and observable progress. Ask for approval before consequential or irreversible actions.
Build representative test sets and rubrics; compare versions across accuracy, completeness, groundedness, task success, latency, cost and harmful failure modes.
Let users review, edit or reject outputs, see important tool actions and return to manual work. Explain limitations without overwhelming every interaction with generic warnings.
Minimise sensitive inputs, protect credentials, test prompt-injection paths, validate outputs, monitor cost/errors and plan model/provider fallback and rollback.
The result should be an evaluated application path with explicit boundaries, measurable behaviour and operational visibility—not just a demo that works on one example.
Target users, task, inputs, success criteria, unacceptable failures, access boundaries and human approval requirements.
Model rationale, retrieval/source plan, prompt/configuration versioning and context freshness approach.
Typed inputs/outputs, allow-listed operations, scoped credentials, timeouts, limits, validation and approval points.
Representative examples, edge cases, scoring rubric, regression tests, human review process and documented limitations.
Interaction design, status/progress, citations where appropriate, editable results, error recovery and manual fallback.
Latency/cost/error metrics, feedback channels, incident handling, version comparison and rollback procedure.
Clear expectations make better projects. These answers describe the decisions usually worth making before work begins.
Discuss your requirementsOnly within clearly defined permissions and risk boundaries. External, destructive, financial or consequential actions should have the safeguards and approval points appropriate to their impact.
Ground answers in approved information, evaluate against representative cases, validate structured outputs, expose sources when useful and provide a way to report and correct failures. No model can be assumed correct by default.
No. Rules, search, smaller models or traditional software may be more accurate, cheaper and easier to maintain. Choose technology against the job and quality target.
Monitor failures, latency, cost and user feedback; rerun regression tests when models or prompts change; use a controlled rollout and rollback path when quality falls.
Examples of the kinds of experiences and systems that this discipline can make possible.
Make it easier to explore, ask and act with context.
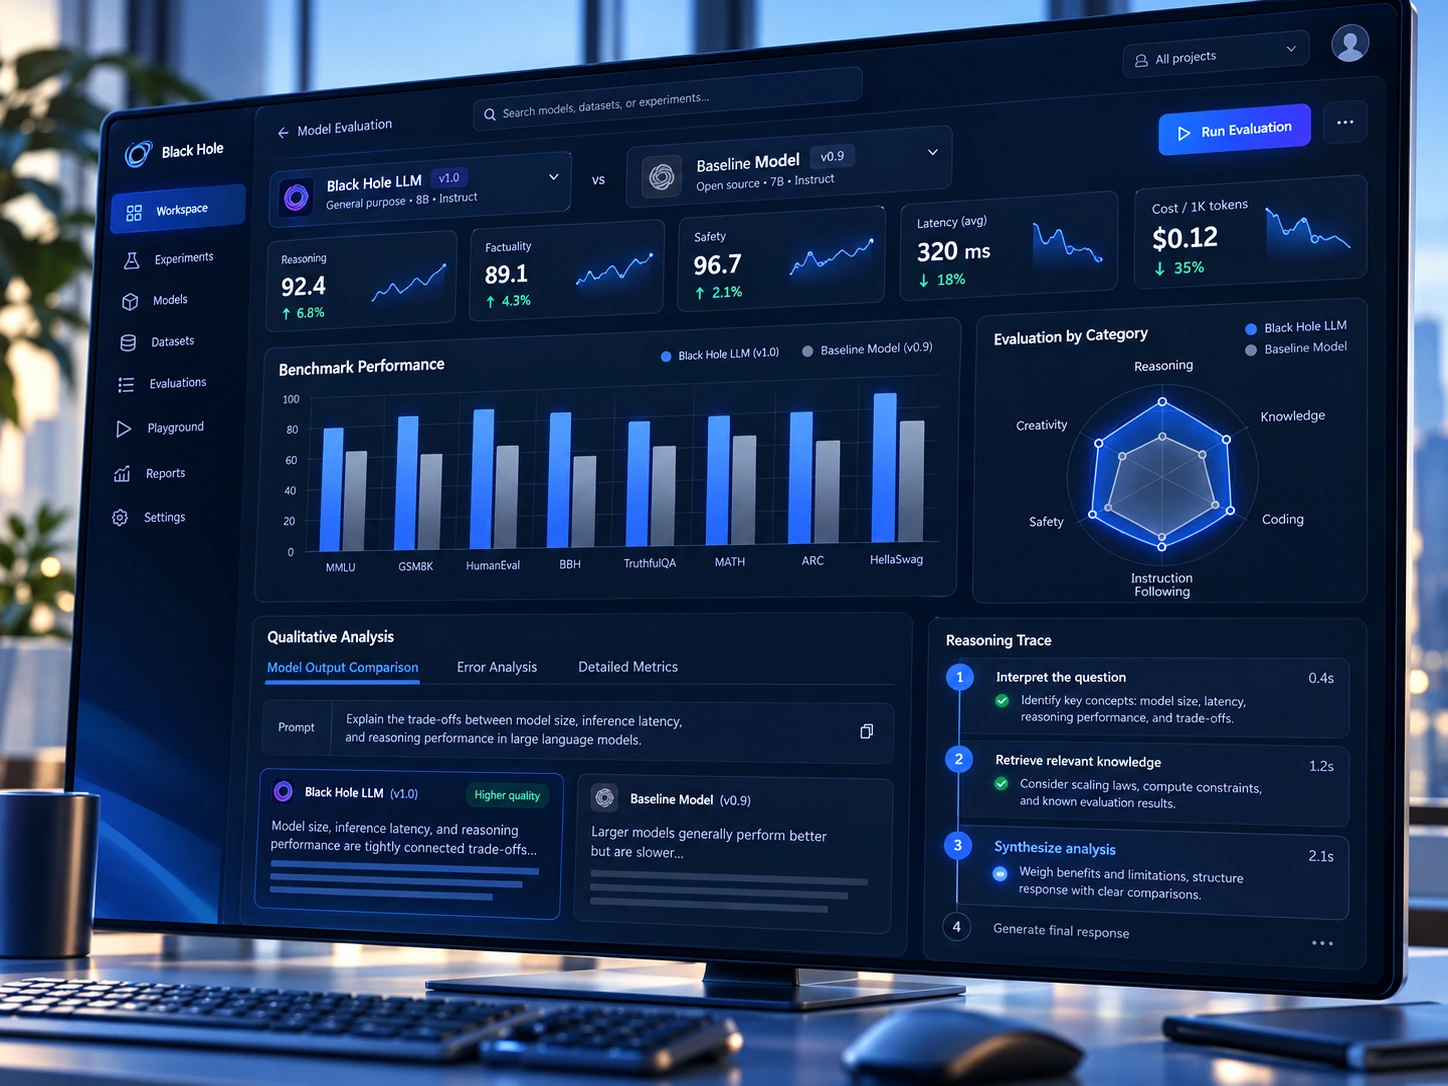
Connect steps in a task while keeping progress visible.
Inspect outputs and improve quality over time.
Bring us the ambition, the problem or the rough sketch. We’ll work through the right next step together.
Connect with Black Hole