Application hosting
Choose runtime and networking patterns based on traffic, dependencies and operational capability.
From hosting to deployment and observability, create a practical foundation for software that has to keep working.
For product teams launching new services, improving delivery or making existing infrastructure easier to operate.
Infrastructure choices shape operating cost, recovery, data protection and the user experience. We would design around actual availability needs—not abstract scale claims.
Cloud architecture is useful when it supports real security, cost, delivery and resilience needs—not when it simply looks complicated.
Choose runtime and networking patterns based on traffic, dependencies and operational capability.
Move tested changes through preview, staging and production with approvals and repeatable deployments.
Make service health, data recovery, alert ownership and infrastructure costs observable.
These building blocks can be tailored to a concrete product need, team and technical environment.
Select a hosting and service model that fits the product, data sensitivity, traffic and team.
Automated build, test and deployment steps with clear environments, approval points and rollback paths.
Storage, backups, migration strategies and access boundaries matched to the lifecycle of the data.
Useful logs, metrics, alerts and runbooks that help teams find and fix problems promptly.
The architecture should make it easy to see where changes enter the system and how teams detect and recover from faults.
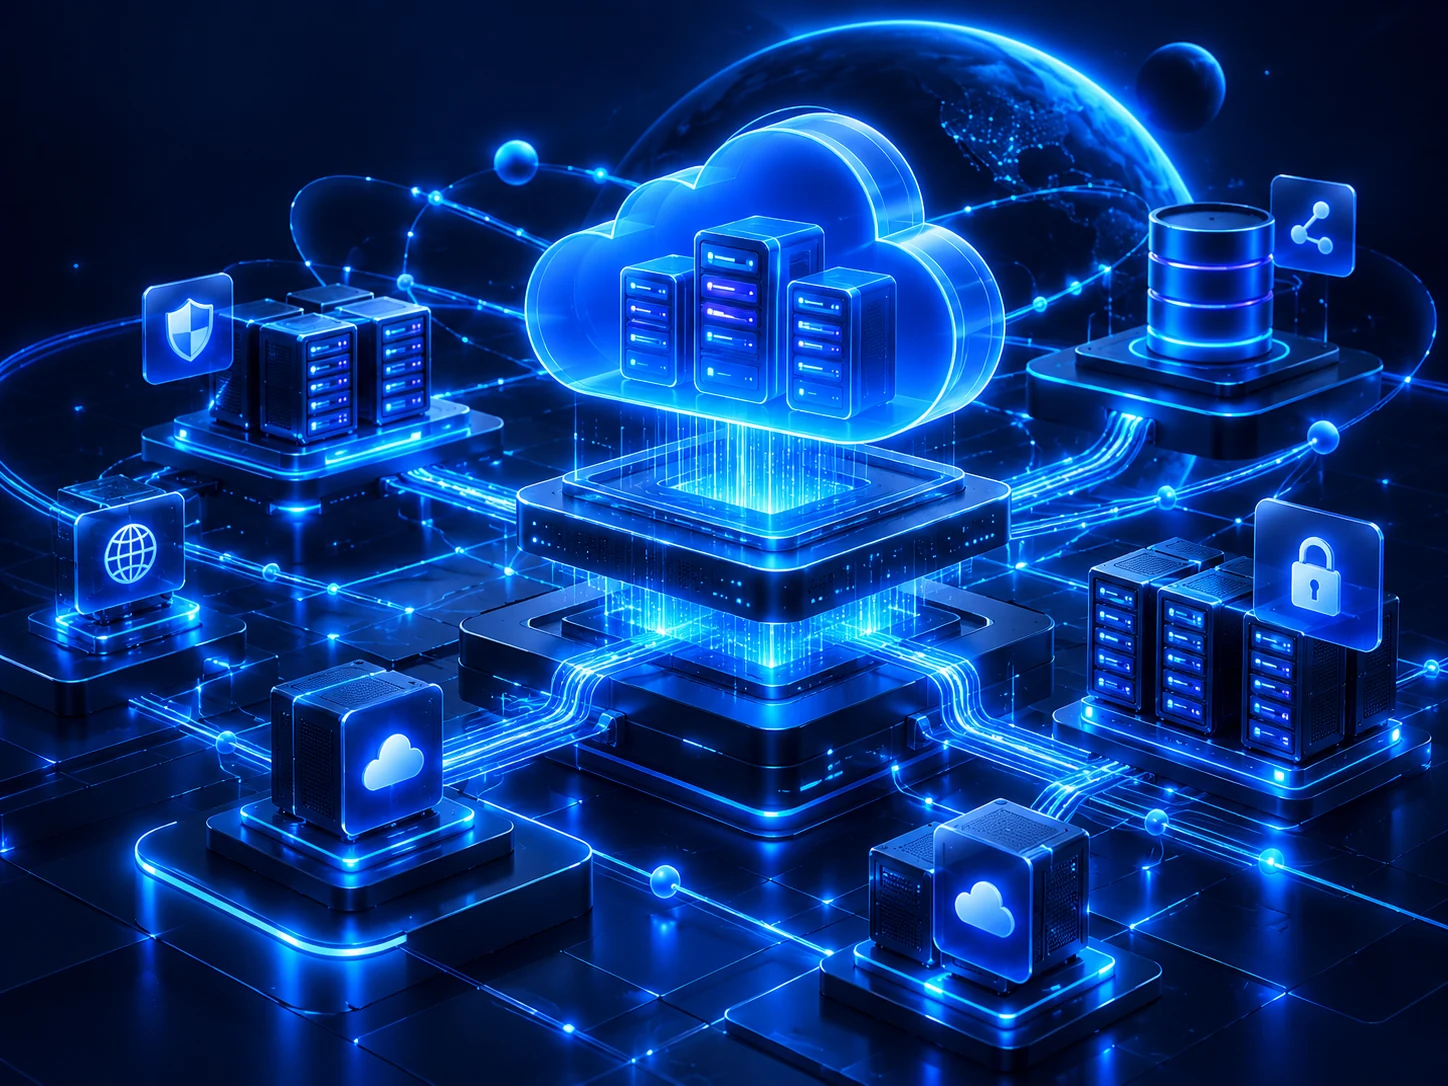 CONCEPT ILLUSTRATION · 02 / 05
HTTPS · Routing · Content delivery
Runtime services · Background tasks · Configuration
Databases · Storage · Backups · Access controls
CI/CD · Observability · Incident response
Availability targets, region choices and recovery objectives must be decided from actual business requirements.
A new web product needs predictable releases, protected data and a straightforward way to diagnose incidents.
Illustrative system journey — not an existing customer case study.Code and configuration are reviewed and validated.
An automated pipeline deploys to the intended environment.
Application, data, network and permissions follow a clear architecture.
Health signals, backups and practiced rollback support recovery.
These are possible applications, not claims about past customer engagements. Every build starts with actual constraints and a defined outcome.
A new application moves from manual deployment to reproducible builds and a clear rollback procedure.
Teams identify bottlenecks and establish sensible scaling limits before adding expensive architecture.
Storage lifecycles, permissions, retention and backup restoration are planned alongside the product.
Use the simplest architecture that can meet realistic needs.
Plan alerts, runbooks and recovery before an incident.
Review consumption, scaling thresholds and budgets over time.
Scope and deliverables depend on the engagement. This is a representative process for planning and building the work responsibly.
Understand workload, data needs and operating constraints.
Choose the smallest dependable service architecture.
Automate setup, delivery and essential verification.
Test recovery, inspect costs and improve real bottlenecks.
Each deliverable is scoped and agreed before work starts.
Share your current hosting setup, release process, data sensitivity, expected workload and recovery expectations.
Technology choices start with understanding the problem—not assuming a particular stack.
Usually not by default. Multi-cloud adds operational complexity and should be justified by a specific availability, regulatory or portability requirement.
Environments, traffic assumptions, security controls, monitoring, backups, recovery objectives, cost and ownership.
Often yes, after reviewing dependencies, stateful services, migration risks and a rollback plan.
Share the idea, the constraints and the result you're aiming for. We'll explore a sensible direction together.